Automation breaks quietly. A scraper that pulled 40,000 product pages on Tuesday returns empty arrays by Thursday, and nobody notices until the pricing dashboard has been stale for two days.
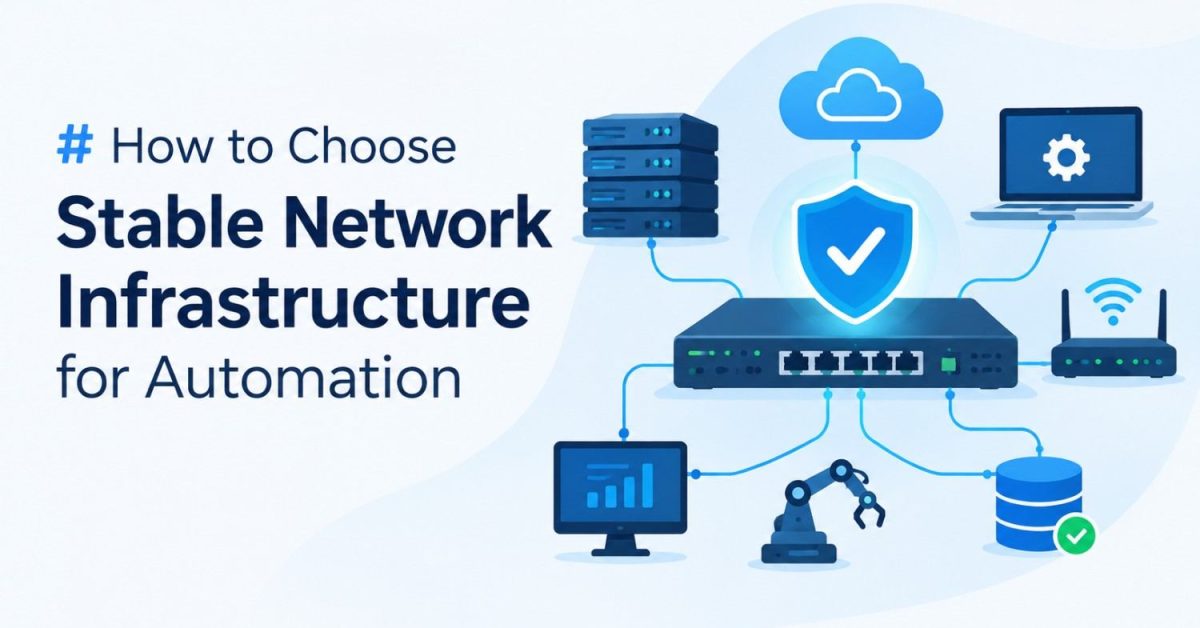
The Python is usually fine. What fails is the network layer underneath it: blocked addresses, half-open sockets, DNS timeouts, and throttling that nobody budgeted for.
Most teams shop for that layer by comparing advertised speeds and monthly price per gigabyte. Those are useful numbers, but they’re the wrong first questions.
Start by Auditing How the Connection Fails
Every network path fails eventually, so the useful question is what the failure looks like from inside the script. A connection that drops with a clean 502 is trivial to retry. One that hangs for 90 seconds and then returns a challenge page wearing a 200 status code will poison a dataset silently.
But silent corruption costs more than downtime. A crawler that returns 200s full of blocked-page HTML for six hours will feed a competitor pricing model garbage, and the analysts downstream have no reason to question it. By the time someone spots the problem, the model has already been retrained.
So the first infrastructure decision is about IP legitimacy, since that determines how often those ambiguous failures happen at all. Addresses registered to internet service providers behave differently from bulk datacenter ranges, which is why teams running long sessions against strict targets often discover IPRoyal’s best isp proxy solutions when datacenter pools stop working.
Protocol Support Decides What Can Be Automated
HTTP proxies handle browser-style traffic and little else. SOCKS5 passes any TCP connection through, which matters the moment automation touches mail servers, database clients, or a headless browser doing WebSocket work.
The SOCKS protocol specification predates most of the tooling built on top of it, and its version 5 authentication model is why credential rotation works cleanly at scale. Providers that only offer HTTP endpoints are quietly capping what the stack can do later.
The authentication method matters too. IP whitelisting removes credential handling but ties the automation to fixed egress addresses, which breaks the day someone moves a worker to a new cloud region. API-based credentials avoid both problems and rotate on a schedule.
Location Beats Raw Throughput More Often Than Expected
A proxy in Virginia hitting an Amsterdam server adds roughly 100ms of round-trip time against a local alternative. Multiply that across 50,000 requests and the fast connection is the slow one.
Geoblocking makes the point sharper. Pricing data on Amazon.de looks different through a German address than an Austrian one, and teams that assume neighboring countries are interchangeable end up rerunning the whole collection.
So pick the country first, then the type, then the budget. Reversing that order is how projects end up with fast addresses in the wrong place.
Treat Rate Limits as Part of the Design
Nothing gets an automation banned faster than ignoring a server’s own instructions. The 429 status code carries a Retry-After header for exactly this reason, and the IETF specification has defined that behavior since 2012.
Most scrapers ignore it. They retry immediately, burn through a pool of addresses in an afternoon, and then blame the provider for weak IPs. Then they ask why the ban rate spiked.
Exponential backoff (start at one request per second, double the wait on each rejection) costs a few minutes of throughput and saves an entire address pool. Session persistence matters just as much: rotating mid-checkout or mid-login breaks state and flags the account.
Judge Providers on Recovery, Not Uptime Claims
Everyone advertises 99.9%. But almost nobody publishes what happens during the other 0.1%, which is the only part that affects a running job. Uptime on the vendor dashboard and uptime on the target site are different metrics.
Google’s engineering teams argue for error budgets over absolute reliability targets, treating a defined amount of failure as something to spend deliberately. Applied to proxy infrastructure, that means asking how many failed requests the pipeline can absorb per day before results become untrustworthy, then buying against that number.
Ask vendors for a 24-hour success-rate log on the exact targets in scope, not a marketing average. Providers running their own hardware can produce it; resellers usually can’t.
What This Looks Like in Two Years
Automation stacks are getting harder to hide every year. Detection systems now score behavior across whole sessions, so infrastructure chosen only to solve the IP question will keep failing in new ways.
The teams that stay ahead build for graceful degradation from the start: clear failure signals and a provider willing to show real numbers. That work is unglamorous, and it’s the difference between a pipeline that runs for two years and one that quietly rots in six weeks.
